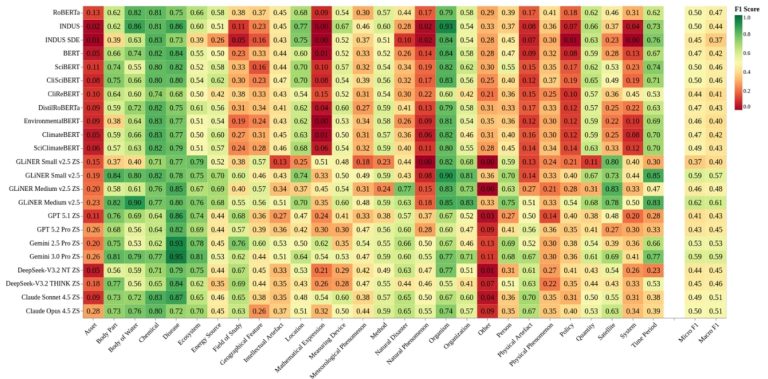
The rapid growth of scientific literature on anthropogenic climate change necessitates automated information extraction to manage and synthesise complex, multi-scalar climate phenomena. Although the research community increasingly relies on natural language processing (NLP), particularly named entity recognition (NER), existing resources in this domain lack broad thematic coverage and rigorous multi-expert validation. To address this gap, […]
Laboratory for Natural Speech and Language processing
Benchmarking Security and Reliability of Open-Source and Commercial Large Language Models in Financial-Domain Scenarios
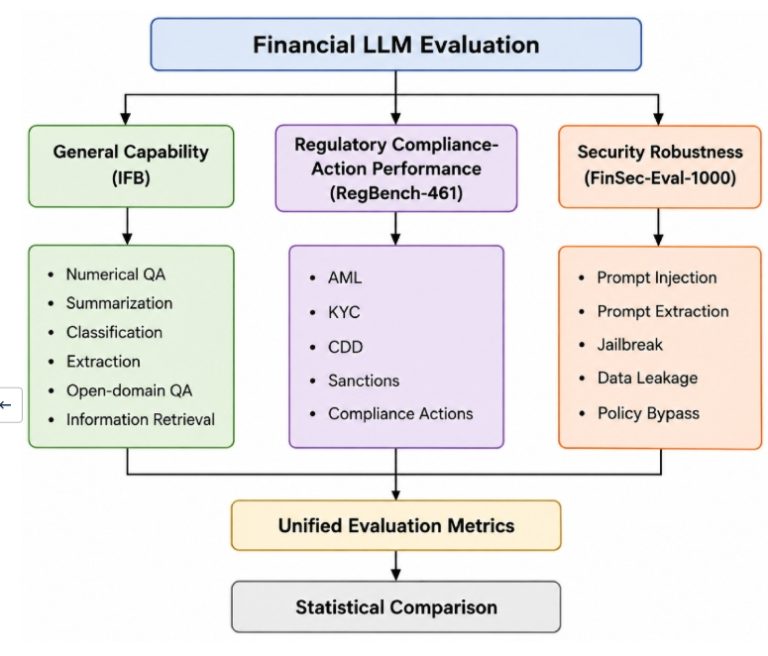
Large language models (LLMs) are adopted in financial services, yet existing benchmarks provide limited insight into financial-domain capability, regulatory compliance-action performance, and security robustness. This study proposes a unified multidimensional evaluation framework for evaluating open-source and commercial LLMs in regulated financial environments. The framework comprises three complementary benchmark components: the Integrated Financial Benchmark (IFB), which […]
Security and Privacy of Large Language Models: Threat Taxonomy, Ethical Implications, and Governance
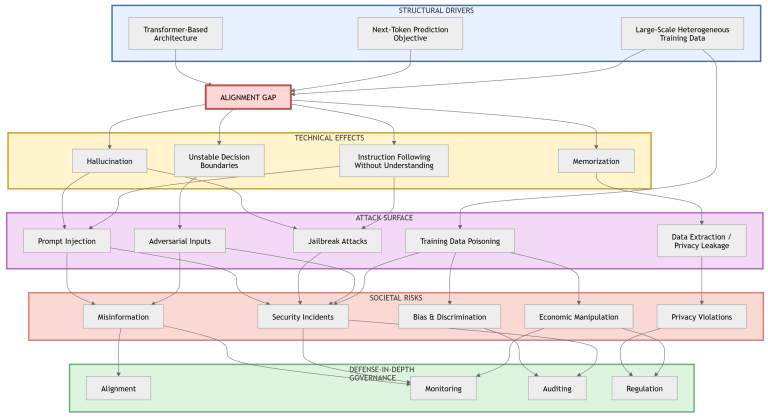
Large Language Models (LLMs) are increasingly deployed across professional and societal domains, introducing security, privacy, and governance challenges beyond traditional software vulnerabilities. Despite extensive research on individual risk categories, a unified lifecycle-oriented perspective connecting architectural properties, adversarial threats, and governance implications remains limited. This review examines security and privacy risks associated with LLMs through a […]
Knowledge Graphs in the Era of Large Language Models (KGELL)
Knowledge Graphs (KGs) have gained attention due to their ability to represent structured and interlinked information. KGs represent knowledge in the form of relations between entities, referred to as facts, typically grounded in formal ontological models. Such machine-readable formats enable AI systems to make decisions using clear and verifiable data. Consequently, KGs have become essential […]
LIVE Quantum – Development of an Integrated AI Platform for Multichannel Personalized Management of User Requests
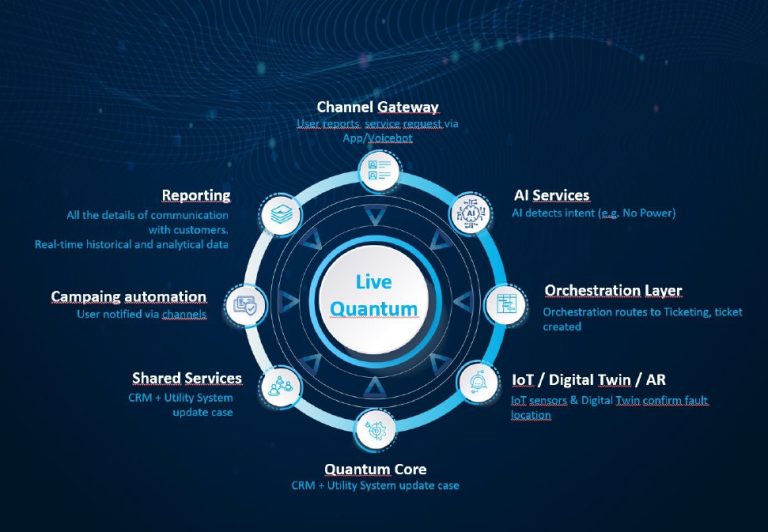
The LIVE Quantum project focuses on the research and development of an advanced, integrated AI-based platform for multichannel, personalized management of user requests, primarily targeting operators of critical infrastructure systems such as energy, water, gas, telecommunications, and utilities. The project combines industrial research and experimental development activities to create a scalable and modular solution that […]
Pretraining and evaluation of BERT models for climate research
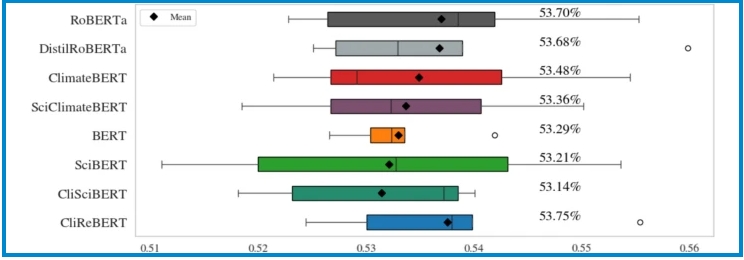
Motivated by the pressing issue of climate change and the growing volume of data, we pretrain three new language models using climate change research papers published in top-tier journals. Adaptation of existing domain-specific models based on Bidirectional Encoder Representations from Transformers (BERT) architecture is utilized for CliSciBERT (domain adaptation of SciBERT) and SciClimateBERT (domain adaptation […]
Interpretable Machine Learning: A Case Study on Predicting Fuel Consumption in VLGC Ship Propulsion
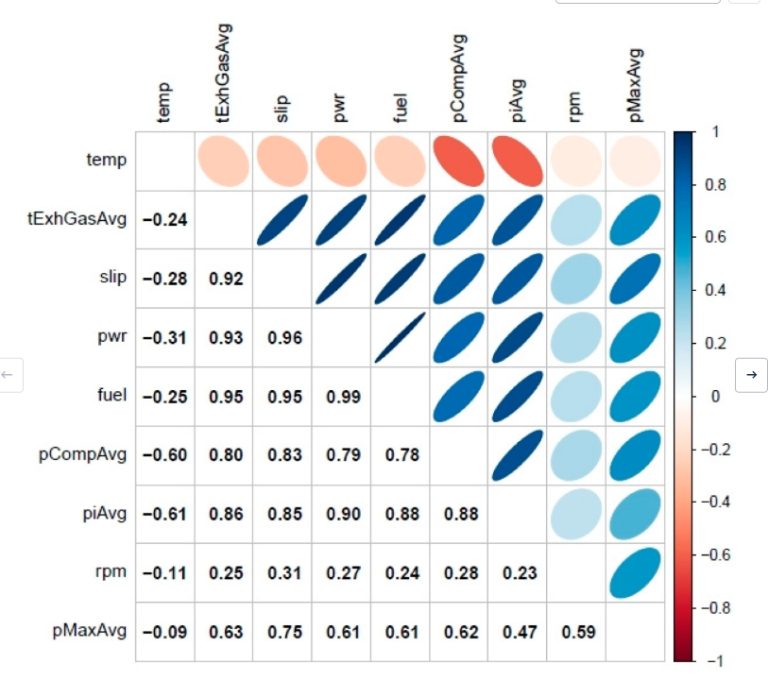
The integration of machine learning (ML) in marine engineering has been increasingly subjected to stringent regulatory scrutiny. While environmental regulations aim to reduce harmful emissions and energy consumption, there is also a growing demand for the interpretability of ML models to ensure their reliability and adherence to safety standards. This research highlights the need to […]
Recursively Autoregressive Autoencoder for Pyramidal Text Representation
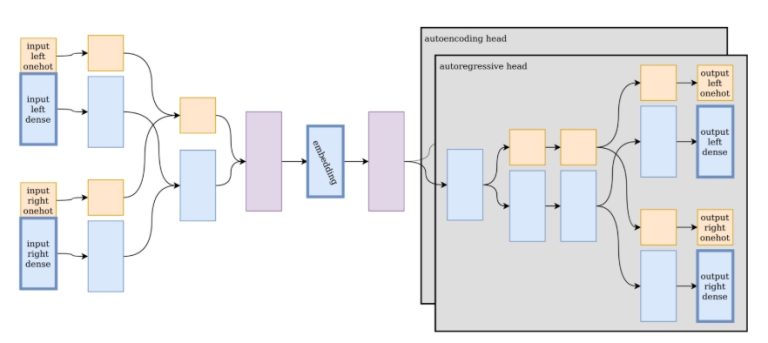
We introduce Pyramidal Recursive learning (PyRv), a novel method for text representationlearning. This approach constructs a pyramidal hierarchy by recursively building representations of phrases, starting from tokens (characters, subwords, or words). At each level, N representations are recursively combined, resulting in N-1 representations on the level above, abstracting the input text from characters or subwords […]
Retweet Prediction Based on Heterogeneous Data Sources: The Combination of Text and Multilayer Network Features
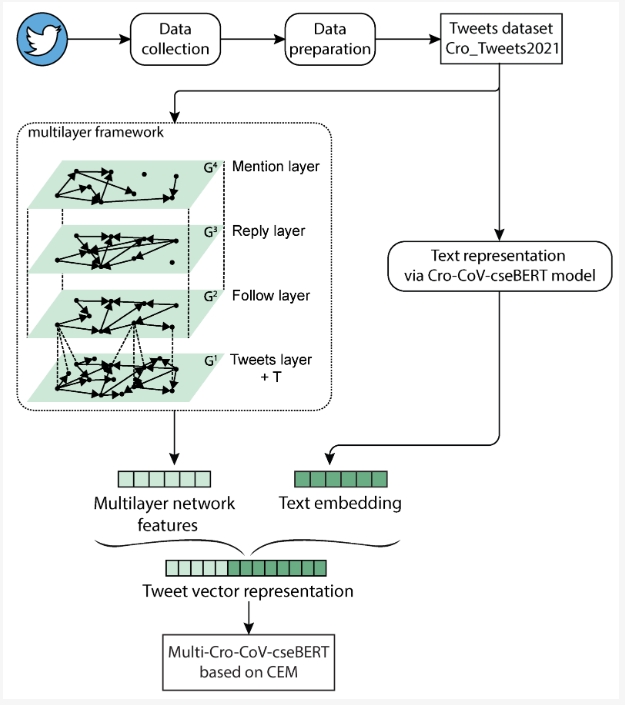
Retweet prediction is an important task in the context of various problems, such as information spreading analysis, automatic fake news detection, social media monitoring, etc. In this study, we explore retweet prediction based on heterogeneous data sources. In order to classify a tweet according to the number of retweets, we combine features extracted from the […]
Neural Natural Language Generation: A Survey on Multilinguality, Multimodality, Controllability and Learning
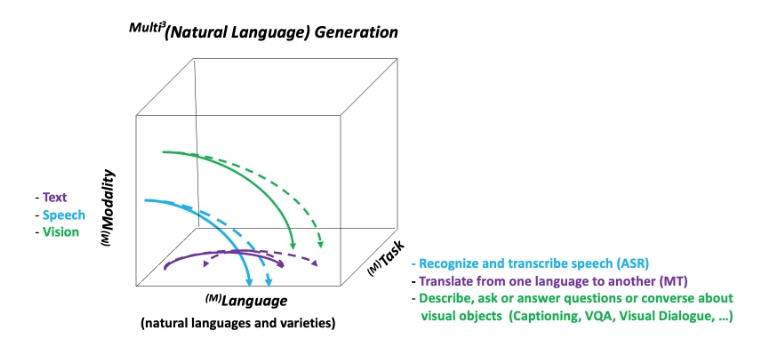
Developing artificial learning systems that can understand and generate natural language has been one of the long-standing goals of artificial intelligence. Recent decades have witnessed an impressive progress on both of these problems, giving rise to a new family of approaches. Especially, the advances in deep learning over the past couple of years have led […]

