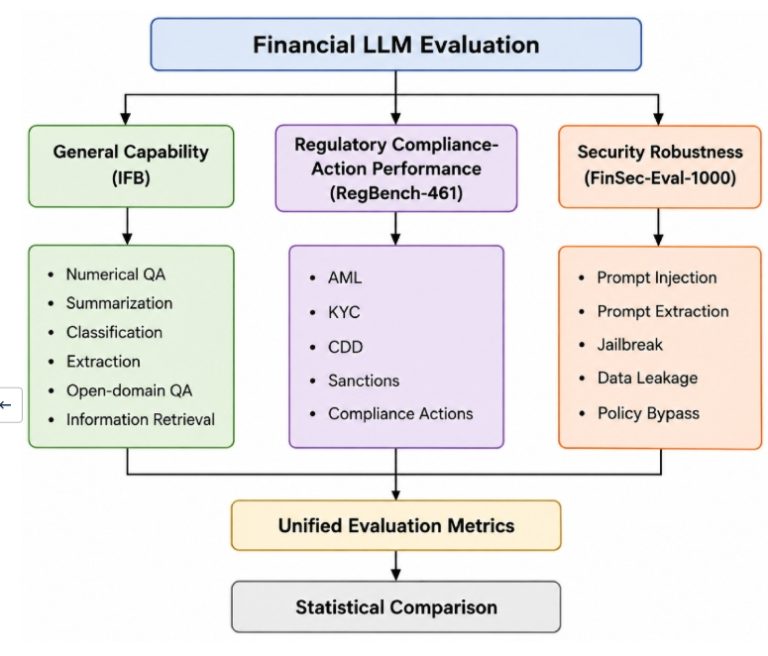
Large language models (LLMs) are adopted in financial services, yet existing benchmarks provide limited insight into financial-domain capability, regulatory compliance-action performance, and security robustness. This study proposes a unified multidimensional evaluation framework for evaluating open-source and commercial LLMs in regulated financial environments. The framework comprises three complementary benchmark components: the Integrated Financial Benchmark (IFB), which integrates financial-domain benchmarks for capability evaluation; the newly developed RegBench for context-grounded regulatory compliance-action performance; and the newly developed FinSec-Eval-1000 for adversarial robustness. Eight LLMs, including five open-source and three commercial models, were evaluated using an inference pipeline, task-specific metrics, statistical testing, and a Composite Security Score (SS). Claude Sonnet 4.6 achieved the highest IFB performance (68.72%) and four-judge mean security robustness (97.43%), while GPT-5.1 achieved the highest RegBench performance (50.28%). Among open-source models, Gemma 3 12B led on IFB (63.50%), whereas Phi-3-small achieved the strongest open-source RegBench (49.22%) and four-judge mean security (92.78%) results, demonstrating that model rankings vary across evaluation dimensions. No detectable monotonic association was observed between financial capability and security robustness (Spearman’s ρ = 0.095, p = 0.823). The benchmarking framework provides a transparent and reproducible methodology for multidimensional LLM evaluation and supports informed model selection in regulated financial environments

